
Introduction: Purpose and scope
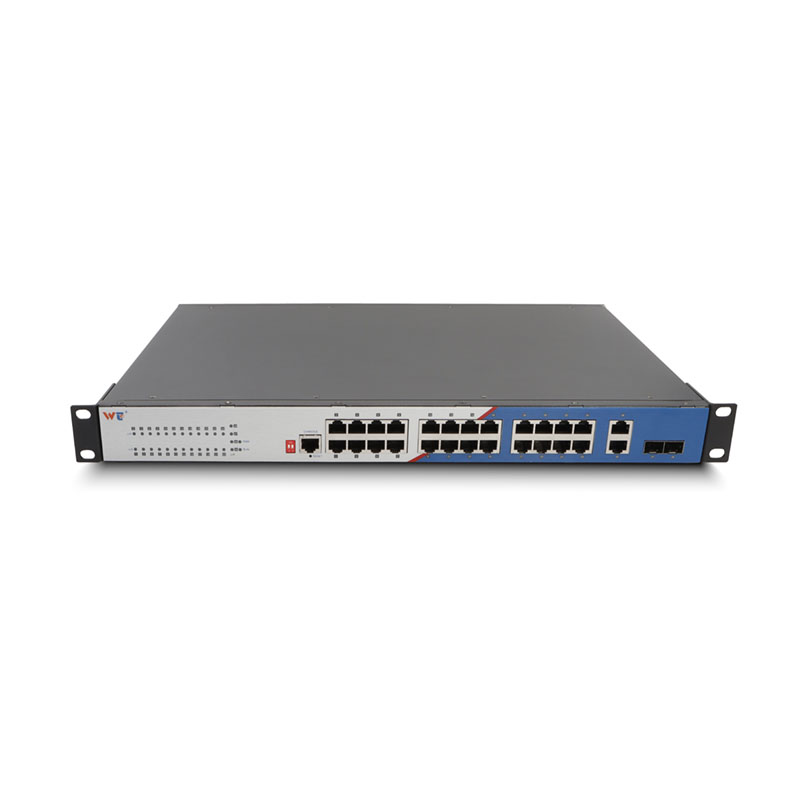
This framework presents clear, stepwise guidance for deploying 50G SFP56 transceiver systems in carrier and large enterprise networks. It is written with practical assumptions: existing fiber plant, available rack space, and managed switching platforms such as a layer 2 managed switch at the aggregation layer. The goal is reliable throughput, deterministic latency, and maintainable operations across dense sites like Ashburn, Virginia, where hyperscale facilities require disciplined design and repeatable processes.
Core components and topology
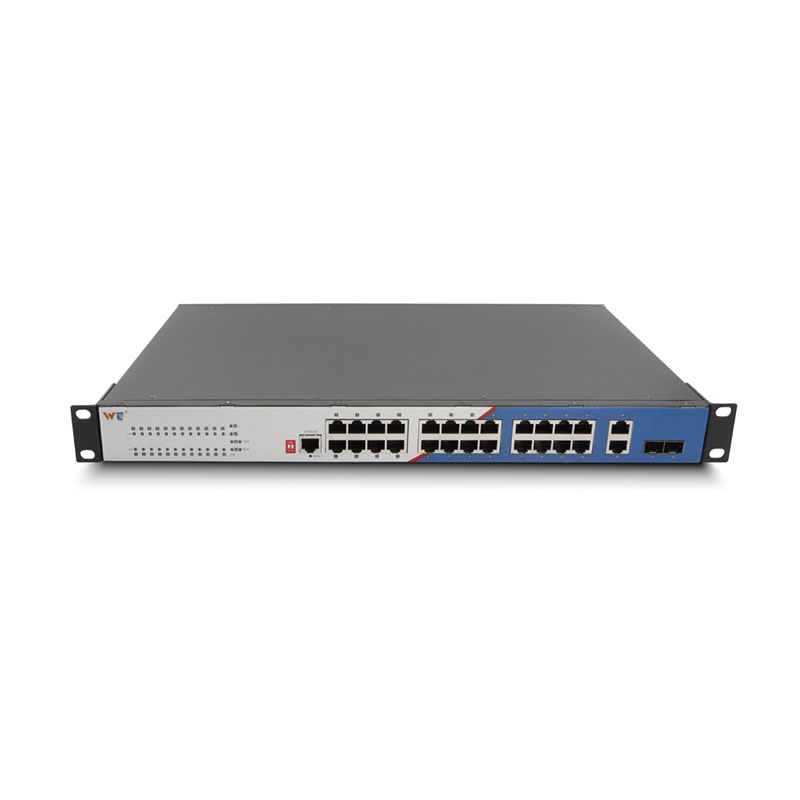
A robust 50G SFP56 architecture rests on three technical pillars: optics, electrical interface, and switching fabric. Use SFP56 transceiver modules that match your fiber type and reach. On the electrical side ensure the PHY and SERDES align with your switch ASIC capabilities. For switching, select a network switch layer 2 that supports 50G ports, VLAN segmentation, and basic QoS shaping. Keep the topology simple: access servers into ToR switches, leaf-spine fabric for east-west, and clear uplinks to core aggregation.
Implementation steps: from lab validation to rack roll
Follow this phased approach to reduce surprises in production.
1. Laboratory validation — perform link burn-in with representative traffic patterns and test link integrity over the intended fiber runs. Include BER and optical power margin checks.
2. Interoperability check — verify SFP56 modules with switch firmware versions and server NICs. Confirm negotiated speeds and auto-negotiation behavior with the PHY and SERDES settings.
3. Staging and configuration — pre-load switch configurations, VLAN maps, and port policies on a staging switch. Test link aggregation groups and failover behavior under controlled failure injection.
4. Controlled cutover — bring new links online during maintenance windows, monitor counters and optics telemetry, and hold short rollback procedures.
At each step, log optics telemetry and port statistics for later analysis. Keep spare modules and a tested DAC cable kit in the rack. Small habit: label transceivers with installation date — it saves troubleshooting time later.
Common pitfalls and operational production teardown
Many faults trace to mismatch between optics and switch settings, contaminated fiber endfaces, or overlooked power-budget issues. During operational production teardown, engineers should record {main_keyword} and {variation_keyword} alongside link counters and SFP part numbers to ensure repeatability. Avoid changing firmware mid-roll. Do not assume all SFP56 modules behave identically across vendors; minor variations in EEPROM descriptors or lane mapping can affect multi-lane alignment. Clean connectors, verify attenuation, and confirm optical power margins before declaring a link healthy.
– Another common mistake is insufficient thermal planning. SFP56 modules dissipate heat; high-density panels without airflow will cause alarms and reduced life.
Testing checklist and diagnostics
Use this concise checklist when troubleshooting or validating new 50G links:
– Optical power and receiver sensitivity compared to module datasheet.
– BER under expected traffic load and during failover events.
– PHY and SERDES lane alignment, and negotiation logs from switch CLI.
– VLAN and QoS behavior across the leaf-spine fabric.
Record each item with timestamps and the rack location. Such records proved decisive during a multi-site roll where Ashburn operators traced intermittent packet loss to a mis-seated patch panel.
Evaluation metrics and golden rules
Three critical metrics will tell you whether an implementation meets carrier expectations:
1. Link stability: measured as sustained error-free uptime over 30 days and verified BER thresholds. This reflects physical and link-layer integrity.
2. Latency consistency: P95 and P99 latency under production load. Carrier-grade systems show tight distributions, not wide variance.
3. Operational repeatability: documented procedures, spare inventory, and successful staged rollbacks during pilot deployments.
Golden rules: pick transceivers and switches from vendors with clear compatibility notes; validate in lab with full telemetry; and maintain strict fiber cleanliness and thermal discipline. These rules lead to fewer surprises and faster mean time to repair.
Deployment discipline matters; it makes a complex stack reliable. For practical equipment and disciplined procurement, consider the product choices and support model from WINTOP. –